Showing posts with label Python. Show all posts

Thursday, 25 August 2022

Home Engine - Blender Export & Model Loading

Some progress in my home engine has been had, first of all multiple geometry rendering through my fixing up and better understanding both render passes and descriptor sets.

All of this is nuts and bolts, what I want to get to; just like the DirectX 11 rendered version; is to play with 3D geometry and placing objects into a scene.

To this end my hand written geometry is no longer hacking it, and you will have seen from my raw game engine posts I did use Milkshape 3D.

Milkshape, lovely as it is to my eye, is not a modern well featured 3D suite and sadly does not let me easily plug into the geometry live within it (one can only export and perform post-processing).

To that end I delved into how one might write a Blender add-on to export your own format...

Long Story short, here's my text intermediate output from just such a plug-in written in python.

The plug-in is far from robust, I followed the lines of another open source plug in and applied my own, copying it into blender with a batch file and clearing the pycache each time I perform an edit.

But it is doing the job I initially want, and I get my own format of file output.

And indeed I can load these into my engine...


I can work on the axis for the data output and start to ensure my camera system from the main client works as expected in vulkan; since the maths here is exactly the same code I don't anticipate any issues.

This should free my mind up to think about a lighting system and to finally get back to where I was with the coloured cubes in the DirectX 11 version and ultimately onto a full scene.

I have four constant things in the world, a ground plane, a skybox and a center marker flag (showing X, Y and Z axis respectively) with a quartet of boxes in the center of the scene.  This is the test scene for the "world" loaded into the scene graph.  And it's where I want this to be this time next week perhaps.

Since progress has been much quicker now I'm past the deep dive into learning the initial set up of vulkan.

I can also appreciate much more why folks just pick up an off the shelf engine, I myself make little prototypes in Unreal Engine 4.  But this kind of denudes me of the walk through these technologies.

For the most part creating an engine like mine, which is planned to have solid shaded low poly vehicular combat, well it's a solved problem, so I'm enjoying following in a lot of well trod foot steps to better my understanding of the processing, memory, mathematics and challenges in writing a game engine.

Friday, 15 February 2019

Coding Standards - About Scopes (again)

Consistency is good, consistency is light, consistency is really what you need think about when creating code, no matter what format, language, platform or project you're on do things the same way, and even on your first pass do them your way consistently before you apply any locally demanded view of the code....

What do I mean by view?  Well, I'm talking about coding standards, but the non-functional side of things, hence the view.  You can look at code from any angle you choose, indeed there are multiple ways to achieve the same solution within code, the difficulty is to get things out there, put them down, then sort the wheat from the chaff.

I've done this in a couple of videos, where I move pieces of code from their own coding layout to my own, I have labelled these "coding standards", but in retrospect they've just the coding view.

One of my big points is the notation for the scope of variables, I love to use scoped notation.  Having been brought into programming when Hungarian notation was not only taught to you academically as required, but demanded by all projects you worked on (basically as you had no code completion tools, so knowing the type of a named variable whenever you utilised it was really very useful) but that was twenty plus years ago, now we have code completion I strongly feel your tools should be made to work for you.

Therefore, when I complete a call or variable name, I want that to communicate something to me, and the most useful is to check the scope, the code completion tells me the type and the name, but scoping isn't really fully covered in the tooling (please post below any suggestions for Visual Studio, Atom, CodeBlocks or Visual Studio Code which perform scope notation or checking on the fly).

When I complete my typing and pause I want to see all the m_ members together, all the c_ constants all the s_ statics and so many coding standards documents define these three.  However, it's just not far enough, what happens when you have locals named 'angle', 'view' and 'Gregorian'?  They're at very different points within the code completion window which pops up, you have to remove your hands from the keyboard to begin scrolling through them; or worse still start typing letters in order to guess the name (for instance we may start to type a c to see if 'Gregorian' comes up actually as 'calendar').

My solution?  The solution I've been pushing time after time, post after post, video after video?  Scope more things.

We can add "local" as "l_", parameters as "p_", we can compound them, so a static constant maybe "sc_" and we can tailor this in whichever manner we feel fits best, but be consistent.

Let me be utterly clear, this is not Hungarian notation of old, we are not adding "i" to integers or "l" to longs, we are not defining the type within the name, we are simply defining the scope and helping the tools to help us by grouping the various scopes of variables together.

I find it incredibly hard to read documents which go half way, defining members as "m_" (or just a leading m) is extremely common, ditto for constants and even statics, it's only with parameters people get a little squeamish.  "p_" is sometimes reserved for pointer, but that's a style edging back to Hungarian you're notifying the reader of the type and use rather than the scope, therefore I push "p_" as a parameter.  But I can also see arguments for "i_" and "o_" for parameters, which tell you it's an input or output to the function.  If one wanted to be a pedant you could go so far as to stress this with "pi_" and "pi_".

This isn't to say I'm for everything, for example in returning from a function:

int foo();

I will not define an "r_" as the return scope, I'm not interested in the semantics to that extent, and I don't feel code like this:

int foo()
{
int r_result(0);

... Some code to set r_result

return r_result;
}

Is communicating anything useful, so often in my code you will find:

int foo()
{
int l_result(0);

... Some code to set l_result

return l_result;
}

As the result remains a local until returned.

Which brings me back to my second bug bear of the month, one which I've already blogged about returning early.  I'll let you remind yourselves of my opinions.


And just a note to the world at large, if you're coding "m_" for members, but ALSO add Hungarian notations "m_iInteger" stop, stop it now... and yes that includes when you're doing pointers "int* m_pIntegerList"... argh, I want to pull my own arm off just to have something to throw at the screen when I see this one, it's a hybrid as annoying as the Alien in Alien Resurrection.


What's my solution?... Well the completely sane idea I use is "m_IntegerListPtr"... Yes, it's a pointer... I tell myself it's one, I'm not strange at all... Alright, maybe a little.


Friday, 10 November 2017

Virgin Media : Poor Internet Speed Misery

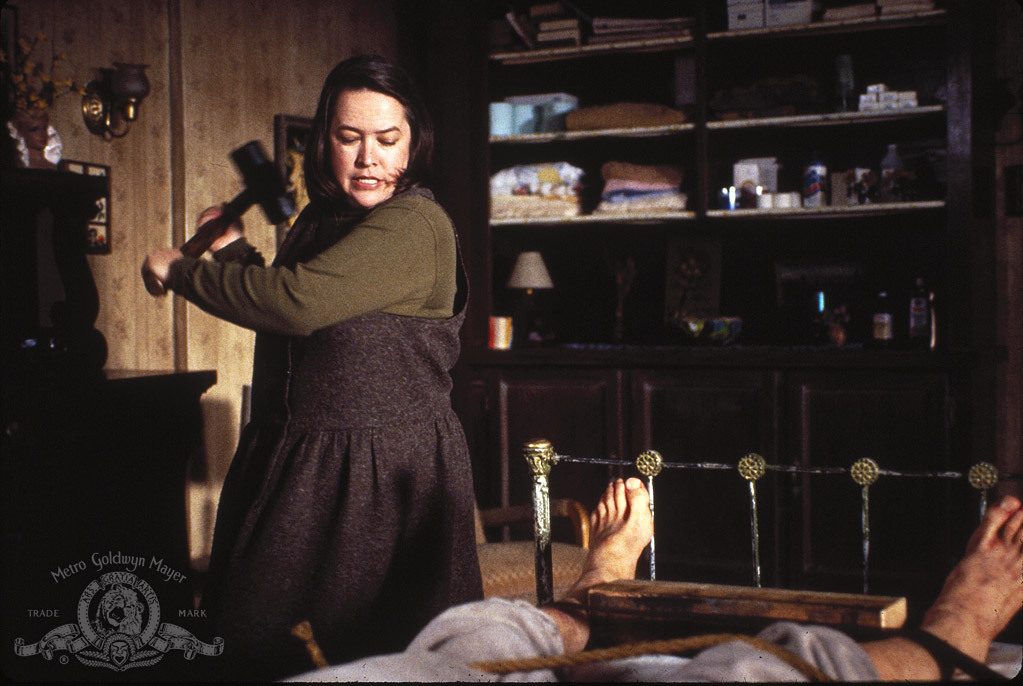
You know that moment in Misery where Annie (played by the excellent Kathy Bates) raises the lump hammer to Paul (James Caan's) ankles?  That hopeless moment, where you know what's coming, and she's determined this is the best, and he's helpless to change things....


Yeah, his feeling at that moment is the same feeling I get whenever I try to solve my service problems with Virgin Media.  I've tried in the phone centre, they either won't talk to me, or deny I'm an account holder - the account being in my wifes name, but I'm a registered up user of the account etc etc.... Or they simply deny there's an issue....

"I can ping you now sir"....

Really, a few ICMP packets get through and you think it's a-okay do you?

Or I get told, reboot your superhub...

Or variously asked "are you on wifi or wired"... It makes no difference when the speed recorded by either is less than 2mbits!!!

And I've just been told in a reply on twitter "If you have been told about an Area Issue were you given an estimate as to when the issue will be resolved"... I've not been told anything about any area issues, nothing, nada, zip.

Therefore I'm still not best pleased, remember I went down from paying through the nose for Vivid200, as I never ever got anywhere near 200mbits/sec ever.  I did record regular speeds of around 34 to 50 mbits, therefore the safer, more cost effective option was to pay for Vivid50.  Simple, see, simple logical option, if they can't meet the expectations of their own service, play the system at it's own game.

However, it seems that in reality, Vivid200 should be labelled Vivid50, and Vivid50 itself should be called Vivid1... Because breaking the 1mbit/sec barrier seems to be too much for it.

I have therefore decided to create something anyone can interpret, a chart... Managers love charts... People can interpret charts....

This chart is going to record the internet speed (recorded from my linux server, on my wired Cat5e directly to my 1gigabit router, which is directly wired to the Virgin Media Superhub 2 set into Modem Mode).  No wifi, no confusion, no bull, and my router has pfSense, so I can see there's no shenanigans, just the pure speed through put.

I'm going to record the speed with "speedtest-cli", which you can see yourself how to install here.

I will collect my results by running a python script, which runs the speed test and outputs the time, the upload and finally the download speed into a CSV file.

Find the source on my github... 

import subprocess
import time
from time import gmtime, strftime

# Open a simple text file for writing the result
resultFile = open("speedtest.txt", "a+")

while True:
# Header text & placeholders for our result
print ("Starting Test...")
timeStr = strftime("%Y-%m-%d %H:%M:%S", gmtime())
downloadSpeed = ""
uploadSpeed = ""

# Action the process to test our speed
# capturing it's output
result = subprocess.run(['speedtest-cli'], stdout=subprocess.PIPE)

# Process the output into text & split the text
# at each new line character
btext = result.stdout
text = btext.decode('ascii')
lines = text.split("\n")

# For each line, check whether it is upload
# or download
for line in lines:
# For Download, take a split against space
# and the middle value is the speed
if line.startswith('Download: '):
speedParts = line.split(" ")
if len(speedParts) == 3:
downloadSpeed = speedParts[1]
# Likewise for upload, the middle  value is
# the tested speed
elif line.startswith('Upload: '):
speedParts = line.split(" ")
if len(speedParts) == 3:
uploadSpeed = speedParts[1]

# Print our output result as a CSV
print (timeStr + "," + downloadSpeed + "," + uploadSpeed)

# Write the result to a file also
resultFile.write (timeStr + "," + downloadSpeed + "," + uploadSpeed + "\r\n")
resultFile.flush()

# Count down until the next test time
count = 10
while count > 0:
# The line is repeated, so we use the end=""
# and a return carriage to print over and over
print ("\rTime until next test " + str(count) + " seconds", end="")
time.sleep(1)
count = count - 1
# Print a new line to stop the next text appending
# on the time count down line
print()

I will then load this CSV file into a spread sheet and create a chart, here's one I created earlier with 5 test data points.


The blue-line is where I'm most concerned, that is my download speed, as you can see within three minutes I had quite a difference, ranging from a high of 2.24 mbit, to a low of 1.23 mbit.  Upload speed has been more consistent giving a measly 3.5 to 4.0 ish.

I already know where VirginMedia will take the conversation, they will talk about "based on average peak time download performance".  However, I want to immediately counter that their speed information states that speeds are based around "Movie based on 4.1GB file size a single user and wired connection", and this chart is provided.... 

Average download speed at peak time (8pm to 10pm) the time's I have mostly messaged to them on twitter are sub 1mbps... Right now at just before 11am they are still reporting as extremely low.  And yes, this server is the ONLY machine on in the house, the wifi is off, the other wire into this hub removed, there is one wire to one machine and one wire to their Superhub...

And yes, I can get 1gbit disk to disk over NFS on this hub, the wires to and from it to the machines are perfect, and I've also swapped the wire to the superhub.

I'm going to run this for a few days, and see what speeds we get in the dead of night, or early mornings, and see if there is a pattern.  I have known for years Virgin will throttle speeds, however, their table of speeds is labelled "Average", one can only believe we're on the lowest ebb of that bell curve, and I am not a happy customer.

Friday, 23 June 2017

Development : My Top Three Testing Tips

I've said before, and I'll say again, I'm not a fan of Test Driven Development, tests and test frameworks have their place, but they should not; in my opinion; be the driving force behind a projects development stream - even if it does give managers above the dev team a warm fuzzy sense of security, or if it allows blame to be appropriated later, you're a team, work as a team and use tests on a per-developer basis as a tool not as a business rule.

*cough* I do go off topic at the start of posts don't I... *heerrhum*, right... Top Three Automated Testing Tips... From my years of experience...


1. Do not test items which are tested by masses of other developers... I'm talking about when you're using a frame work of library, ensure you are using it correctly certainly, do this at training or with your coding standard, but then do not labour the point by re-testing... Lets take a good example of this, the C++ Standard Library.

The Standard Library contains many collection classes, these classes have iterators within, lets look at a vector:

#include <vector>

std::vector<int> g_SomeNumbers { 1, 3, 5, 7, 9 };

We could iterate over the collection and output it thus:

int g_Sum(0);
for (int i (0); i < g_SomeNumbers.size(); ++i)
{
    g_Sum += g_SomeNumbers[i];
}

However, this is not leveraging the STL properly, you are introducing the need to test the start poing "int i(0);" the end condition "i < g_SomeNumbers.size();" and the iterator "++i", three tests, slowing your system down and complicating your code base.

int g_Sum(0);
-- TEST SUM START
-- TEST i COUNT START
-- TEST RANGE CONDITION LIMIT
for (int i (0); i < g_SomeNumbers.size(); ++i)
{
    -- TEST ITERATION
    g_Sum += g_SomeNumbers[i];
    -- TEST SUM CALCULATION - THE ACTUAL WORK DONE
}
-- REPORT TESTS

Using the iterator, we leverage all the testing of the STL, we remove the need to range test the count variable, we remove the need to test the condition and leave only the step as a test to carry out...

int g_Sum(0);
for (auto i(g_SomeNumbers.cbegin()); i != g_SomeNumbers.cend(); ++i)
{
    g_Sum += (*i);
}

Our code looks a little more alien to oldé timé programmers however, it's far more robust and requires less tests simply because we can trust the STL implementation, if we could not thousands, hundreds of thousand of developers with billions of other lines of code would have noticed the issue, our trivial tests show nothing of gain, so long as we've written the code to a standard which uses the interface correctly...

int g_Sum(0);
-- TEST SUM START
for (auto i(g_SomeNumbers.cbegin()); i != g_SomeNumbers.cend(); ++i)
{
   -- TEST ITERATION
    g_Sum += (*i);
   -- TEST SUM CALCULATION - THE ACTUAL WORK DONE
}
-- REPORT TESTS


2. Do now allow values which have been tested to change unexpectedly... I'm of course talking about "const", which I have covered before on these pages, but constness in programming is key.  The C family of languages allow constness at the variable level, you may notice in the previous point I used a const iterator (with cbegin and cend) as I do not want the loop to change the values within the vector... Constness removes, utterly, the need to perform any tests upon the integrity of your data.

If it's constant, if the access to it is constant, you do not need to test for mutations of the values.

Your coding standard, automated scripts upon source control submissions, and peer review are your key allies in maintaining this discipline, however it's roots stretch back into the system design and anlysis stages of the project, to before code was cut, when you were discussing and layout out the development pathway, you should identify your data consider it constant, lock it down, and only write code allowing access to mutable references of it as and when necessary.

Removing the need to retest mutable calls, removing the need to log when a mutable value is called because you trust the code is key.

In languages, such as python, which do not directly offer constness, you have to build it in, one convention is to declare members of classes with underscores to intimate they are members, I still prefer my "m_" for members and "c_" for constants, therefore my post-repository submit hooks run scripts which check for assigning to, or manipulation of "c_" variables.  Very useful, but identified by the coding standard, enforced by peep review, and therefore removed from the burden of the test phase.


3. Remove foreign code from your base... I'm referring to code in another language, any scripting, any SQL for instance, anything which is not the pure language you are working within should be removed from the inline code.

This may mean a stored procedure to store the physical SQL, rather than inline queries throughout your code, it maybe the shifting of javascript functions to a separate file and their being imported within the header of an HTML page.

But it also includes the words we ourselves use, be that error messages, internationalisation, everything except code comments which is in whatever language you use (English, French etc etc) should be abstracted away and out of your code.

Your ways of working, coding standards, analysis and design have to take this into account, constness plays it's part as well, as does mutability, where ever you move this language to, and whatever form it takes test it a head of time, and then redact that test from your system level tests, trust you did it right based on the abstraction you've performed.  Then avoid burdening your system throughout the remaining development cycle.

One could expand this to say "any in-house libraries you utilise, trust their testing" just as I stated with the STL in my first point, however, I am not talking about code, I am talking about things which are not code, which are uniquely humanly interpretable.

The advantage of removing them and pre-testing the access to them is that you retain one location at which you have an interlink, one place at which a value appears, one place where they all reside and so you leverage easily converting your programs language, you leverage easily correcting a spelling mistake, and all without needing to change your system code; perhaps without needing to even re-release or re-build the software itself (depending on how you link to the lingual elements)

Ultimately reducing the amount of testing required.

Wednesday, 10 May 2017

Development : Python, MySQL and Protocol Buffers Build

Today I've come to a totally virgin installation upon a server, this was for a work group I've got to head up whom are looking at pushing MySQL with Python.  And things initially went wrong...

I stipulated they had to use Python3 and thought everything else would be fine for them to install with Pip3, so...

sudo apt-get update
sudo apt-get upgrade
sudo apt-get install python3
sudo apt-get install python3-pip
sudo apt-get install mysql-server

Everything looked fine, their user could install packages through Pip3 and they had Flask and a few other things and were flying.  I used the mysql client on the command like to test I could add a few items and also ran...

sudo mysql_secure_installation

To do the basic hardening of the database, so everything was fine... Right?....RIGHT?!?!

No, not exactly.... "I can't get mysql.connector".... Came the cry.

And they were right, it reported a myriad of build issues and could not install.  I took a look... NIGHTMARE!

It appears the installation of mysql.connector via Pip3 depends upon Protocol Buffers from google for the latest version of mysql.connector... Which the Pip install didn't sort out, at least not easily... Luckily I run a whole gaggle of virtualized machines, so I could quickly spool up a new instance and try a few things out...

This is the script I came up with....

cd ~
sudo apt-get update
sudo apt-get upgrade
sudo apt-get install -y python3-pip git autoconf automake libtool curl make g++ unzip
sudo pip3 install flask
hostname -f > hostname.txt
sudo apt-get install -y mysql-server
sudo mysql_secure_installation
sudo ldconfig
cd ~
git clone http://github.com/google/protobuf.git
cd protobuf/
./autogen.sh
./configure
make
make check
sudo make install
sudo ldconfig
cd python
sudo python ./setup.py install
cd ~
sudo ldconfig
sudo pip3 install mysql-connector --install-option='--with-protobuf-include-dir=/usr/local/include/google/protobuf' --install-option='--with-protobuf-lib-dir=/usr/local/lib' --install-option='--with-protoc=protoc'

Lets go through this step by step...

cd ~
sudo apt-get update
sudo apt-get upgrade
sudo apt-get install -y python3-pip git autoconf automake libtool curl make g++ unzip

This is just the basics, so our installation will now depend upon git, autoconf, automake, libtool, curl, make, g++ and unzip, most all your standard distributions will contain packages for these, we use -y just to skip any permission requests.

sudo pip3 install flask
hostname -f > hostname.txt

The next step is simply a couple of items for our project, we're going to use Flask to provide a restful interface, and the "hostname.txt" is simply to remove our need to call "hostname" again later.

sudo apt-get install -y mysql-server
sudo mysql_secure_installation

Our next step is to install and secure the MySQL service.

sudo ldconfig
cd ~

Generic code now, to simply reload the library list and change to the home directory.

git clone http://github.com/google/protobuf.git
cd protobuf/
./autogen.sh
./configure
make
make check
sudo make install

This is the build of protocol buffers from google, so we pull it from their github repo, we move into that folder, prepare and configure the build, then make the whole build.  By far this is the LOOOONGEST instruction, on a single core 1GB equipped virtual instance this took around 45 minutes.

Once complete we simply need to reload the libraries again...

sudo ldconfig

However, protocol buffers are still not installed within Python, so we are still in the "~/protobuf" folder, we now need to go deeper, into the python folder and perform the setup installation under python...

cd python
sudo python ./setup.py install

When complete we again need to reload the libraries...

sudo ldconfig

And the final, secret sauce, is to actually install mysql connector through pip3 with protocol buffers...

sudo pip3 install mysql-connector --install-option='--with-protobuf-include-dir=/usr/local/include/google/protobuf' --install-option='--with-protobuf-lib-dir=/usr/local/lib' --install-option='--with-protoc=protoc'

This is a single command, spanning one single line.

And voila, once complete you get to use mysql.connector in your python code...

import mysql.connector
import gc

con = mysql.connector.connect (user='whatever', password='something', host='localhost', database='yeahyeah')

con.close()
con = None

gc.collect()

You can find out more about why I nullify and garbage collect a connection in my previous post.

Monday, 8 May 2017

Software Development : Get Constant in C++

What does "const" mean to you?  Does it just mean a value can not be changed?  If so, you may want to read on!

Const is one of those things, which though not unique to C++ is given more meaning when you leverage C++ fully, const allows you to not only define a value as invariant, but also to instruct other programmers coming to your code how a value should be used, how when it is passed as a parameter it should be treated and ultimately how to protect data from needless alteration, de-synchronisation or simple corruption.

Const is therefore your friend, and if you've come to C++ from C, Java, C#, Python or one of the other myriad of languages which don't treat const with as much relevance as C++ you may want to read more than I can say on the topic. 

Bjarne Stroustrop (the inventor of C++) and other authors on the topic (notably Scott Meyers & Herb Sutter) explain in much more detail than I ever could, but for brevity here are two examples of const from my own coding standard which I implore you to digest.

1. Initialise Const Values in the constructor ONLY....

Any instance of the "Ex" class can now access it's "Pi" value, and we communicate to all viewers that the value is a constant and only edited in one place.

2. Where-ever possible pass values as constant references....

We know for certain that the "p_Radius" parameter being passed is NOT to be changed by the function, this is important when you are thinking about letting code document itself, and easily accomplished with "const", and especially annoying when using a language lacking const!

Whatever you do, use const consistently, this needs no specific explanation here, however if you begin following my second rule, you must stick to it!  Don't change half way through a program, if you import a third party API which is not using const in the same way, abstract that third party interface away with a series of your own shims, to make it correct for your usage (the compiler will optimise all these layers away) to leave you with consistent and more easily maintainable code.

You can find must much more about const-correctness elsewhere, I'd start here.

Wednesday, 5 April 2017

Development : Anti-Hungarian Notation

Whilst cutting code I employ a coding style, which I enforce, whereby I output the scope of the variable being used with a prefix.

"l_" for Local
"m_" for Member
"c_" for constant
"e_" for enum

And so forth, for static, parameter and a couple of others.  I also allow compounds of these, so a static constant would be:

"sc_"

This is useful in many languages, and imperative in those which are not type strict, such as Python.

Some confuse this with "Hungarian Notation", it's not.  Hungarian notation is the practice of prefixing a type notification to the variable name, for example "an integer called count" might be "iCount".

I have several problems with anyone using Hungarian Notation, and argue against it thus. With modern code completion and IDE lookup tools this is really not needed, with useful and meaningful naming of your variables the type is not needed and finally there are multiple types with the same possible meaning... i.e. "bool", "BYTE" and "std::bitset" are they all 'b'?  What about signing notation, so you compound "unsigned long" as "ul" to the name?

It all gets rather messy, a good name is enough.

However, the scope of the variable might change, the scope might not be enforced, and in none strict languages you might have a variable go out of scope and then automatically re-create the value with a blank value, if you don't follow your scopes.

Therefore I can justify my usage and enforcement of this coding standard.

What I can't stand however is when someone listens to my explaining this, they read my coding standards document, they even go as far as having me reject their code during peer review for these reasons, and then they dismiss my comment with the "it's just Hungarian Notation"... Scope is not type, and type does not define scope, don't be fooled!

Friday, 31 March 2017

Linux Server Admin : Bash Kill Processes By Common Name

On my Linux server I've recently wanted to go through and kill a bunch of application instances in one go, this is a server where students have been connecting and running carious programs under python, therefore I want to remove from my processes anything called "python".

We can see these in our bash shell with the command:

sudo ps -aux | grep python

To remove all these programs I create the following bash shell script:

k = 0
for i in $(ps -aux | grep python)
do
  k=`expr $k + 1`
  kill -9 $i  
done
logger -s "Closed $k Python Instances"

Notice k=`exp... this is NOT a single quote (apostrophe) it is the "smart quote" on a UK English keyboard this is the key to the left of the number 1.  It is used to substitute the command into place, so the value counted in K becomes the result of the expression "$k + 1", i.e. K+1.  More about Command Substitution in Bash here.

The call to logger -s places the message both on screen and in syslog for me to review later.

This simply loops through all the applications resident and kills them off, I've saved this as a "sh" file, added executable rights with "sudo chmod +x ./killpythons.sh" and I created this to run as a cron job everyday at 3am (a pretty safe time, unless I have some students burning the candle at both ends).

That's everything about the bash script, for those of you wondering about the students, they're those folks following my learning examples from my book, which you can buy here.


Tuesday, 14 February 2017

Programming : Python MySQL Connector Debug

Today, I was asked to look at a server for a friend, their problem... "It just stops working after a few days"... A few days turned into "between three and five".  Doing some mathematics I found they had between 125 and 350 unique visits to the server, each unique visit represents one customer or one remote unit of their fleet.

They relay their data from these to individual database instances on one MySQL Server, so there is about 30 customers each with many unique databases.

The problem?... Well, I find this very distressing, as they open one connection for each arriving remote client, use it and then they closed it... Right... RIGHT?!??!!

import mysql.connector

l_total = 0
while (True):
    # Count
    l_total += 1
    l_res = l_total % 100
    if l_res == 0:
        print (l_total)

    # Open a connection
    con = mysql.connector.connect(user='root', password='***', host='localhost', database='Pickles')
    cursor = con.cursor()

    # Query
    query = ("SELECT * FROM VeggiePatch")
    cursor.execute(query)

    # Retrieve the data
    cursor.fetchall()

    # Close the query cursor
    cursor.close()

    # Close the Connection
    con.close()

This is my test code based on the way their production code works, as having read the error log I see the problem is in the connector constructor and delves down into the networking code.

This of course crashes after around 33,000 cycles.

They're not willing to change their script "willy-nilly", I in fact think they're petrified I've found this problem.  Googling around I don't find any official explanation of this error, only anecdotal forum posts about the MySQL Connector not cleaning up after itself and so reusing the sockets fails over time.


The better solution is to garbage collect the connection each cycle...

import mysql.connector
import gc

l_total = 0
while (True):
    # Count
    l_total += 1
    l_res = l_total % 100
    if l_res == 0:
        print (l_total)

    # Open a connection
    con = mysql.connector.connect(user='root', password='***', host='localhost', database='Pickles')
    cursor = con.cursor()

    # Query
    query = ("SELECT * FROM Tickets")
    cursor.execute(query)

    # Retrieve the data
    cursor.fetchall()

    # Close the query cursor
    cursor.close()

    # Close the Connection
    con.close()
    con = None

    gc.collect()


I also tried to garbage collect each time I printed the the "total", each 100 passes, but this still crashed, the fixed loop here has so far done just under half a million cycles without issue....